
NVIDIA A100
Rent an A100 80 GB server.
$355.99 a month , no KYC .
A dedicated NVIDIA A100 with
80 GB HBM2e , ~2.0 TB/s 3.84 TB NVMe for data- Ready in
1 to 24 hours No KYC , crypto only
01Plans & pricing
One A100 80 GB server, 3 jurisdictions .
The GPU is yours alone, with NVMe storage and an unmetered
| GPU | VRAM | CPU | RAM | Storage | Locations | Price | Order |
|---|---|---|---|---|---|---|---|
   |
|
$355.99/mo
Cheapest competitor |
Deploy |
No GPU plan in this jurisdiction yet: or compare them.
RTX 4090 , 5090, L40S, A100, H100- CUDA drivers preinstalled
- Single and
multi-GPU nodes No KYC · BTC, ETH, XMR, USDT, SOL
Need more bandwidth or FP8? The H100 has the same
02Specifications
The A100 80 GB , in numbers.
NVIDIA’s specifications for the card, and what comes with it in our server.
| Specification | |
|---|---|
| Architecture | NVIDIA Ampere |
| CUDA cores | 6,912 |
| GPU memory | |
| Memory bandwidth | ~ |
| Tensor cores | 3rd generation: TF32, BF16, FP16, INT8 |
| FP16 / BF16 tensor (dense) | 312 TFLOPS |
| FP64 | 9.7 TFLOPS, 19.5 with tensor cores |
| CPU, RAM, storage | |
| Network | |
| Price | $355.99/mo, about $0.488 per hour |
03Sizing
What runs on 80 GB .
The highest precision at which a dense language model fits with an
| Model size | A100 ( | L40S ( |
|---|---|---|
| 7–8B | ||
| 13–14B | ||
| 32B | ||
| 70B | Does not fit | |
| 123B | Does not fit | Does not fit |
LoRA
04Monthly or hourly
When a month beats paying by the hour.
At $355.99
| If the hourly rate is | Our month equals | |
|---|---|---|
| $1.50 per | 33% of the month | |
| $2.00 per | 24% of the month | |
| $3.00 per | 16% of the month |
Hourly rates are examples, not quotes from any provider. We bill monthly, quarterly (−5%) or yearly (−12%), from your balance.
05Use cases
What an A100 is best at.
Fine-tuning LoRA and QLoRA runs on private data that never leaves the server.
Large models on one card
A 70B model at
4-bit , or a 32B model at16-bit , without splitting it across GPUs.Data-heavy jobsEmbeddings and batch inference over large datasets, with
3.84 TB NVMe next to the GPU.Scientific computing
FP64 at 9.7 TFLOPS, 19.5 with tensor cores, for simulations that consumer cards run slowly.
06Jurisdictions
Where A100 servers run.
The same price in each of these jurisdictions.
-
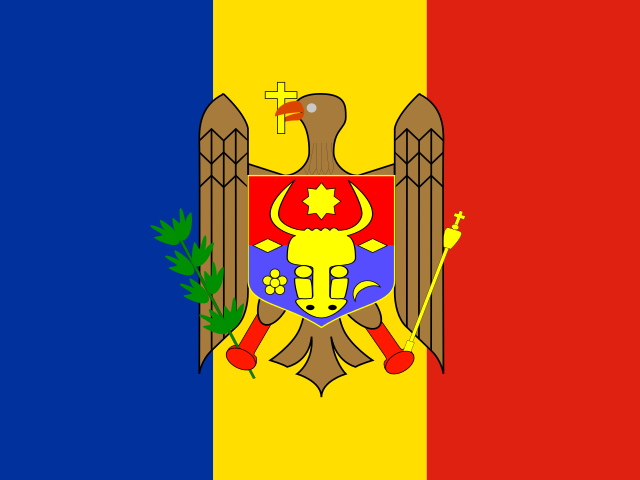
MoldovaChișinăuBest value
Outside the EU
· no DSA London~33 ms New York ~113 ms Singapore~129 ms -
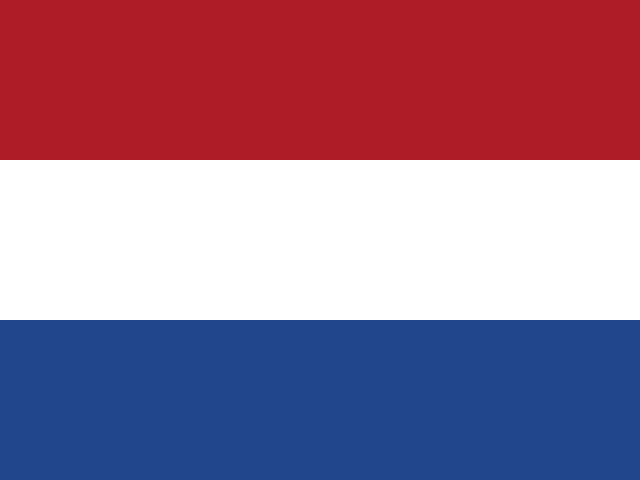
NetherlandsAmsterdamNetwork hub
EU member
· DSA applies London~7 ms New York ~87 ms Singapore~154 ms -
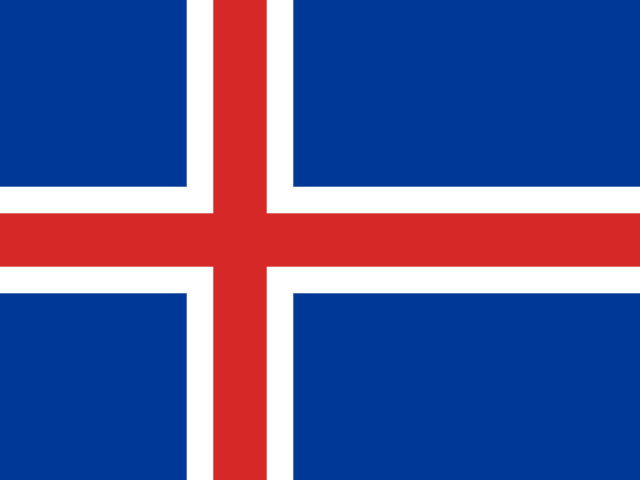
IcelandReykjavík
Free-speech haven EEA· outside the EU· no DSA London~29 ms New York ~63 ms Singapore~169 ms
Latency figures are estimates from distance, not measurements. Every jurisdiction has the same prices. How we estimate latency
07Offshore, in writing
The rules, before you pay.
What we promise is written into our policies, not just our marketing.
US DMCA noticesNot actionedAnswered with our policy, never enforced. Only a local
DMCA policycourt order , or a valid EU notice in EU locations, can require action.IdentityEmail only
No name, address, phone or ID document, ever. A private or disposable address is fine.
Privacy policyPayment5 cryptocurrencies
Bitcoin, Ethereum, Monero, USDT and Solana, paid
Crypto paymentson-chain from any wallet to your balance. No card processor, no chargebacks.TransparencySigned canary
A
Warrant canaryPGP-signed warrant canary every quarter and a public count of every request we receive.
08FAQ
A100 servers, answered.
Another question? The full FAQ answers what people ask before an order: payments, privacy, complaints and support.
Read the full FAQA100 or H100?
Both have
Does the A100 support FP8?
No. FP8 arrived with the H100. The A100 runs TF32, BF16, FP16 and INT8, and quantized models such as
Can I rent it by the hour?
No. Billing is monthly, quarterly (−5%) or yearly (−12%), paid from your balance. At about $0.488 an hour around the clock,
How fast is delivery?
Between 1 and
Are the driver and CUDA installed?
Yes, on the
Can I get a refund?
GPU servers are not refundable once delivered, because the hardware is set aside for you. Check the specifications above before you order.
80 GB of GPU memory, offshore.
- 1Pick a jurisdiction
- 2Pay in crypto,
no ID asked - 3SSH in within
1 to 24 hours